Once you’ve decided to tokenize sensitive data, the next decision is architectural. Do you keep a vault that maps every token to its original value, or generate tokens with a cryptographic process so there is nothing to store? Both approaches are reversible, both can preserve the format of the original data, and both appear in production payment and data platforms. They fail in different ways, scale in different ways and carry different compliance implications.
This guide explains how vaulted and vaultless tokenization work, compares them on performance, security and compliance, walks through a worked example and gives you a framework for choosing. If you need a refresher on the fundamentals first, start with what data tokenization is.
The Short Answer
Vaulted tokenization generates a random token and stores it against the original value in a secure database, the vault. Reversing a token means looking it up. Vaultless tokenization generates tokens with a cryptographic process, such as format-preserving encryption or pre-generated token tables, so nothing is stored per value. Reversing a token means running the process backwards with the same key.
Vaulted gives the cleanest separation between token and data and makes individual records easy to revoke. Vaultless scales and distributes more easily, but concentrates risk in the key.
How Vaulted Tokenization Works
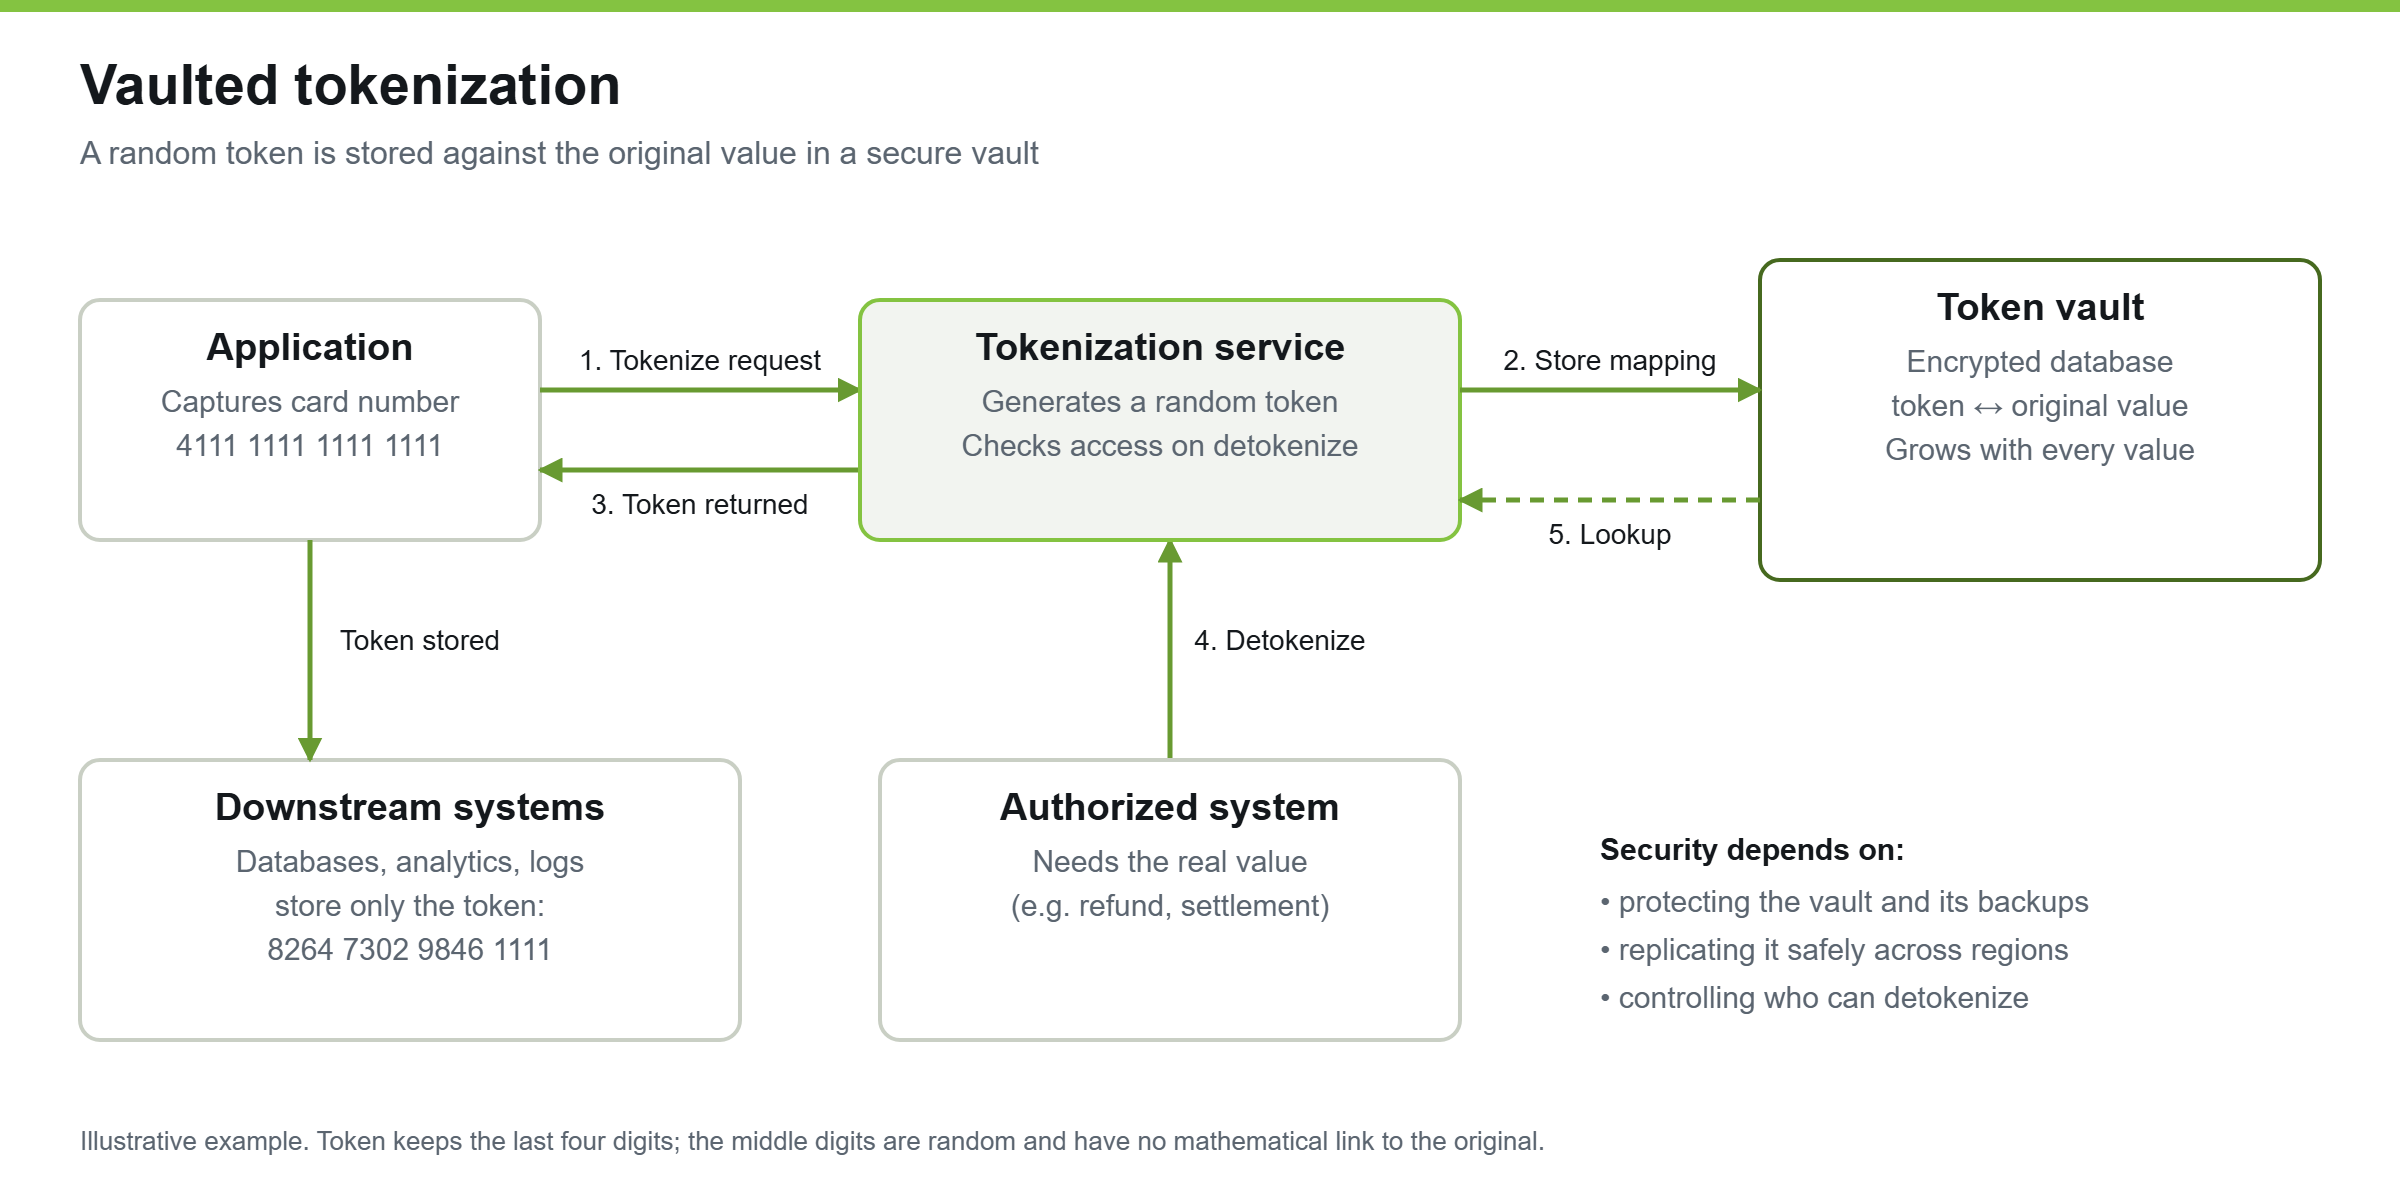
In a vaulted model, the tokenization service sits in front of an encrypted database that holds every token-to-value mapping.
- An application sends a sensitive value, such as a card number, to the tokenization service.
- The service checks whether the value has already been tokenized. If it has and the system issues consistent tokens, it returns the existing token.
- If not, it generates a random token, often in the same format as the original and sometimes keeping the last four digits, and confirms it is unique.
- It stores the mapping in the vault, with the original value encrypted, and returns the token.
- When an authorized system needs the original, it calls the service, which checks permissions, looks up the token and returns the value.
The defining property is that the token has no mathematical relationship to the original value. Someone who steals tokens, or the algorithm that produced them, learns nothing. The trade-off is that the vault becomes a high-value target. It has to be encrypted, backed up, replicated and access-controlled to the same standard as the data it replaces, and it grows with every distinct value you tokenize.
How Vaultless Tokenization Works
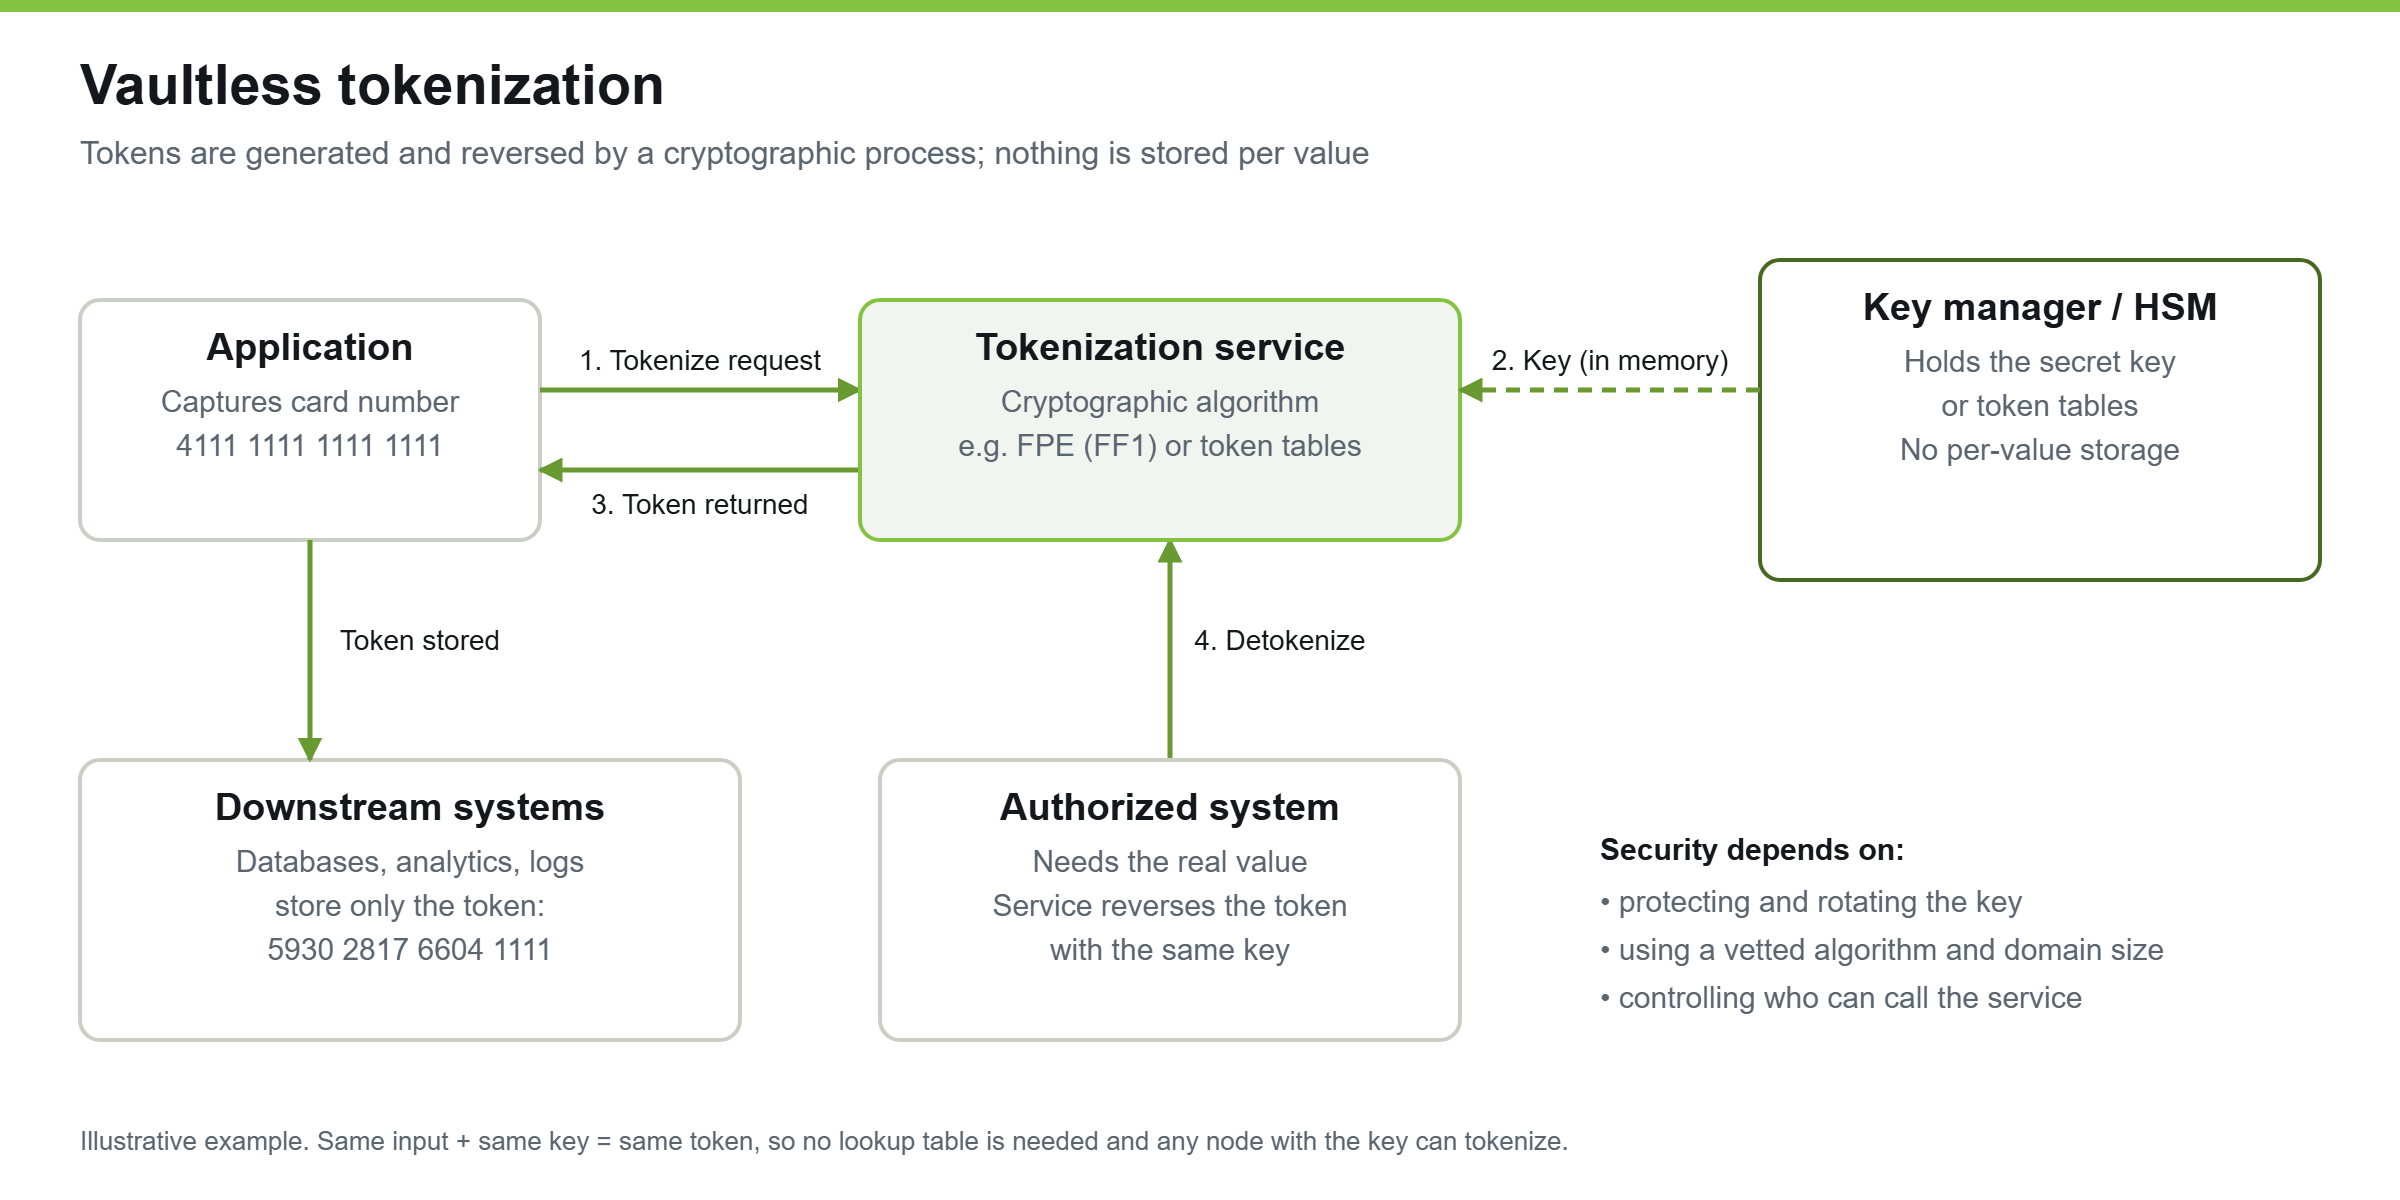
Vaultless tokenization removes the per-value database. The tokenization service derives each token from the original value and a secret, and reverses it with the same secret. There are two common approaches.
- Format-preserving encryption (FPE). The token is the original value encrypted with an algorithm that keeps its length and character set, such as the FF1 mode defined in NIST SP 800-38G. Reversing the token means decrypting it with the same key.
- Static token tables. The service uses fixed tables of random substitutions, generated in advance and distributed to each node. The value is split into pieces and each piece is substituted through the tables. The tables stay the same size however much data you tokenize. Implementations vary by vendor.
Because the same value and the same key always produce the same token, vaultless tokenization is deterministic by default. That keeps joins working across systems, much like deterministic masking does for masked data. Any node that holds the key or tables can tokenize and detokenize locally, with no central database to call.
The trade-off is that the key, or the token tables, become the crown jewels. Anyone who obtains them can reverse every token they produced. Algorithm choice also matters. Short fields give FPE a small domain to work with, which weakens it, and NIST revised its FF3 mode after published attacks. Use a vetted mode such as FF1, follow current NIST guidance on minimum domain size, and keep keys in an HSM or key management service.
Vaulted vs Vaultless Tokenization: Side-by-Side
| Criteria | Vaulted | Vaultless |
|---|---|---|
| How tokens are created | Random value, checked for uniqueness | Derived from the value and a secret key or token tables |
| How tokens are reversed | Lookup in the vault | Cryptographic reversal with the same key or tables |
| Link between token and value | None; the token is random | Mathematical, protected by the key |
| What you must protect most | The vault, its backups and replicas | The key or token tables |
| Storage growth | Grows with every distinct value | Fixed; nothing stored per value |
| Latency | Network call plus database read or write | Local computation; typically lower |
| Multi-region scaling | Needs consistent replication of the vault | Distribute keys or tables; nodes work independently |
| Consistent tokens for joins | Optional; requires a lookup before issuing | Built in for a given key |
| Revoking one person’s data | Delete the mapping and tokens become unresolvable | Harder; delete the tokens or use per-record keys |
| Key or secret rotation | Re-encrypt the vault; tokens can stay the same | New key changes tokens; stored tokens must be re-tokenized |
| Compliance scope | Vault and tokenization service stay in scope | Keys, tables and tokenization service stay in scope |
Performance and Scaling Trade-Offs
In a vaulted system, every new value means a uniqueness check and a database write, and every detokenization means a read. At high volumes the vault becomes the bottleneck. Running in more than one region adds a harder problem: replicas must stay consistent so two regions never issue different tokens for the same value, or the same token for different values. Caching helps with latency, but a cache of token mappings is sensitive data in its own right.
Vaultless systems are compute-bound instead. Tokenization can run as a local library, a sidecar or a service in each region, and it scales roughly in line with the compute you add. Only keys or tables need distributing, not data. That makes vaultless the common choice for high-throughput pipelines, data warehouses and globally distributed applications.
Security Model
The two models put the critical secret in different places. With a vault, an attacker who steals tokens has nothing; they need the vault or access to the detokenization service. With vaultless tokenization, an attacker who obtains the key can reverse every token it produced, wherever those tokens have been copied.
Rotation is where this shows up operationally. Rotating the encryption key on a vault re-encrypts the stored values while the tokens themselves stay the same. Rotating a vaultless key changes every token, so stored tokens must be re-tokenized or the service must support versioned keys.
In both models, the control that matters most is who can detokenize. Most real-world exposure comes from service accounts and applications with broader detokenization rights than they need, not from breaking the tokenization itself. Grant detokenization narrowly, log every request and review the logs.
Compliance Implications
This section is general guidance, not compliance or legal advice. Confirm your approach with your assessor or privacy team.
- PCI DSS. Tokenization can reduce the scope of the cardholder data environment, because systems that only see tokens and cannot detokenize may fall outside it. The vault or the keys and tables, and the tokenization service, remain in scope. PCI SSC guidance also distinguishes tokens that can be reversed cryptographically from those that can only be resolved by lookup, which can affect how assessors treat systems holding them.
- GDPR. Reversible tokens are generally pseudonymised data, not anonymous data, under either model. The right to erasure is easier with a vault: delete one mapping and that person’s tokens become unresolvable everywhere. With vaultless tokenization, you need to delete the tokens themselves or design per-record keys.
- Data residency. With a vault, the location of the vault and its replicas decides where the original data lives. With vaultless tokenization, the original data is not stored by the service at all, but the location of keys and who can use them still matters.
Worked Example: Tokenizing a Card Number
A retailer runs checkout in two regions, analyses orders nightly and needs to process refunds. It tokenizes card numbers at checkout. The card number below is a standard test number and the tokens are illustrative.
With a vault
- Checkout in region A sends
4111 1111 1111 1111to the tokenization service. - The service checks its index, finds no existing token, generates the random token
8264 7302 9846 1111and stores the encrypted card number against it. - The order database and the nightly analytics only ever see the token, and repeat customers can be matched because the service returns the same token for the same card.
- For a refund, the payments service, which has detokenization rights, requests the original. The lookup is checked and logged.
- Region B must reach the same vault, or a consistent replica. If it issued its own tokens, the same card could end up with two different tokens.
Without a vault (FPE)
- Checkout in either region sends the same card number to a local tokenization service holding key K, retrieved from the key manager.
- The service encrypts the digits with FF1 and returns
5930 2817 6604 1111. Both regions produce the same token without talking to each other or storing anything. - For a refund, the payments service asks the tokenization service to decrypt the token with K.
- If K is ever exposed, every token produced with it can be reversed. If K is rotated, the stored tokens must be re-tokenized.
When to Choose Each
Choose vaulted tokenization when:
- You need to revoke or erase individual records cleanly.
- You want tokens with no mathematical link to the original value.
- Volumes are moderate and the vault can sit close to the applications that use it.
- A payment processor or provider already runs the vault for you.
Choose vaultless tokenization when:
- You need high throughput and low latency, for example in data pipelines or warehouses.
- Applications run across several regions or at the edge.
- You want to avoid operating a growing database of sensitive values.
- You need consistent tokens for joins across many systems.
Many platforms support both, and some organisations use a vault for payment data and vaultless tokenization for analytics. And if nobody ever needs the original value back, as is usually the case for test and development data, tokenization may be more than you need. See how tokenization compares with masking before you commit to running token infrastructure.
FAQ
Is vaultless tokenization just encryption?
FPE-based vaultless tokenization is, technically, format-preserving encryption. The difference is mostly in how it is packaged and controlled: tokens replace values across systems, and a dedicated service governs who can reverse them. Table-based vaultless approaches work differently and are not standard encryption.
Which is more secure, vaulted or vaultless?
Neither is inherently more secure. Vaulted tokenization concentrates risk in the vault; vaultless concentrates it in the key or tables. The quality of key management, access control and detokenization auditing matters more than the model you pick.
Can vaultless tokens collide?
An FPE mode such as FF1 is a permutation, so for a given key and domain each input maps to a unique token. Vaulted systems must check for collisions when they generate random tokens.
Does vaultless tokenization remove systems from PCI DSS scope?
It can reduce scope for systems that only handle tokens and cannot detokenize. The tokenization service and the keys or tables remain in scope.
DataOpsZone is an Enov8 resource. Links to Enov8 pages are included where they add detail.